Reaching 99.99% uptime for issuer processing requires card issuers to anticipate failures before they happen. Learn how to get there step by step, from cloud redundancy and failover mechanisms to real-time monitoring, security and compliance.
March 26, 2025
Achieving near-perfect uptime is not just a technical aspiration, it's a business imperative. Payment providers, especially those involved in issuer processing, must deliver relentless reliability to keep transactions flowing smoothly. After all, every second of downtime translates to potential revenue loss and tarnished reputations.
Key Takeaways
Cloud Redundancy: Utilise cloud redundancy and failover mechanisms to avert outages
Understanding SLAs: Comprehend the nuances of Service Level Agreements to set realistic expectations
Advanced Monitoring: Implement proactive and AI-driven monitoring for real-time issue detection
Regulatory Compliance: Balance rigorous compliance with high-availability strategies
Case Study Insights: Learn from DECTA's strategies for maintaining impressive uptime
Why Uptime is Critical in Issuer Processing
Uptime is critical for a payment processor. When transactions are processed all the time, customers are happy, the payment processor stays in the good graces of banks and regulators, and it builds its brand reputation.
The opposite is true for downtime; dissatisfied customers and retailers, expensive fines, and processors who jeopardize their ability to compete with their competitors.
Issuer processing is the layer that receives authorization requests from Mastercard, Visa or UnionPay, checks the card, the balance and the fraud rules, and returns an approve or decline decision in real time. It also covers clearing, reconciliation and card lifecycle management.
Because every card payment depends on that authorization response, issuer processor uptime is felt directly by cardholders: if the processor is unreachable, a card is declined at the checkout, the ATM or the online store, even when the account has funds.
What Happens When an Issuer Processor Goes Down
Card schemes offer a fallback for these moments. Visa Stand-In Processing (STIP) and Mastercard Stand-In Processing can approve or decline transactions on the issuer's behalf when the issuer or its processor does not respond in time.
Stand-in decisions follow limits the issuer sets in advance, so they are a safety net rather than a replacement:
approvals are typically capped
real-time balance checks are not available
the issuer carries the credit and fraud risk of any transaction approved without its own checks
every stand-in transaction also has to be reconciled once the processor is back online
The more often an issuer relies on stand-in, the more risk and manual work it absorbs, which is why high availability in issuer processing matters even with a scheme fallback in place.
This is why cloud redundancy and failover mechanisms are the first step. When you have your workloads on multiple servers and data centers, there's a safety net to ease the burden when failing components arise.
Redundancy ensures that operations can remain the same with one node down, and when you introduce cross-zone replication, geo-failover, and load distribution, you have some of the greatest protections against downtime. For example, geo-failovers allow systems to fail over to other sites if an entire regional outage occurs.
Run your card programmes on 99.99% certified uptime
Authorization switching, 3D Secure v2.2 and card lifecycle management on a PCI DSS Level 1 platform for Mastercard, Visa and UnionPay issuers.
Key Challenges in Achieving Maximum Uptime for Issuer Processing
Achieving maximum uptime for issuer processing presents several key challenges, with infrastructure vulnerabilities being a primary concern. Unexpected hardware failures, software glitches, and network disruptions, including those caused by Internet Service Providers, can lead to downtime if not properly managed. To maintain seamless operations, issuers must proactively anticipate potential failures and implement robust mitigation strategies to safeguard their processing infrastructure.
Then there are cybersecurity threats. DDoS attacks, fraud, and API breaches complicate things more each day to maintain and operate successfully. For example, DDoS attacks hold systems hostage, and having overly cautious security to avoid shutdowns is critical.
Another issue is peak transaction volumes. When a company is trying to sell or transact (Black Friday, the holidays), transaction overload can take place if systems are not set up to support the traffic. The only way to avoid peak transaction overload is to have a scalable infrastructure and predictive capacity planning.
Another issue is third-party dependencies. Many companies work with cloud-based firms and banking network integrations which require third-party integrations for processing. While these can create efficiencies, they often make systems compromised due to more levels of failure.
Therefore, companies should foster healthy relationships with their third-party connections and be honest within a reasonable period of time when integrations go wrong.
Compliance & regulatory constraints reign supreme as well: PCI DSS, GDPR, and PSD2. The certainty of high availability is required to fulfil such standards; therefore, maintaining compliance where no systems can ever go down is critical for the future of the organization.
In the EU, the Digital Operational Resilience Act (DORA) raises the bar further: since January 2025, banks, payment institutions and e-money institutions must manage ICT risk, report major ICT incidents and oversee critical third-party providers, which makes the resilience of an outsourced issuer processor a regulatory matter, not only a technical one.
Uptime benchmarks: Understanding 99.9%, 99.99%, and 99.999% SLAs
Understanding uptime benchmarks is crucial when evaluating Service Level Agreements (SLAs), particularly the differences between 99.9%, 99.99%, and 99.999% availability. These SLAs define expected service levels, ensuring both providers and customers have clear, realistic expectations.
This is the beauty of understanding Uptime Tiers; you understand what level of service you can afford to offer.
Uptime tier
99.9%
99.99% ("four nines")
99.999% ("five nines")
Allowed downtime per year
8.76 hours
52.56 minutes
5.26 minutes
99.99% availability, often called "four nines", means you can afford to be down 52.56 minutes a year, or roughly 4.4 minutes a month, what a difference! To want "five nines" or 99.999% Uptime means you can afford to be down 5.26 minutes a year, because that's all you're allowed!
What to Check in a 99.99% Uptime SLA
The headline percentage only tells part of the story. Before relying on a 99.99% uptime SLA from an issuer processor, card issuers should check:
Measurement period: whether availability is calculated monthly or yearly, since a yearly figure can hide a long outage in a single month
Scope: whether the figure covers real-time authorization only, or also 3D Secure authentication, APIs, clearing files and reporting
Maintenance windows: whether planned maintenance counts as downtime or is excluded from the calculation
Recovery targets: the Recovery Time Objective (RTO) and Recovery Point Objective (RPO) the processor commits to after a failure
Service credits and reporting: what happens if the target is missed, and how incidents are reported to you
Best Practices for High Availability in Issuer Processing
Implementing best practices for high availability issuer processing requires intentional system design and operational consistency. By leveraging robust architectures, redundancy models, and failover mechanisms, issuers can ensure service continuity and minimize downtime, safeguarding the reliability of critical transaction processing systems.
Multi-Region and Multi-AZ Architectures
One of the optimal solutions for High Availability is a Multi-Region and Multi-AZ (Availability Zone) Architecture. These multi-dimensional designs incorporate cloud redundancy and failover mechanisms to guarantee that downtime is never experienced.
Workload distribution across regions and availability zones minimizes the potential for localized failures in one location.
Multi-Region and Multi-AZ Architectures ensure that your systems are protected against Single Points of Failure. The implementation of load distribution between locations means that even if one region experiences regional outages, systems can fail over in seconds with appropriate redundancies.
The key steps to implement such architectures include:
Load Distribution: Distributing workloads across various resources so that one resource isn't overloaded
Cross-Zone Replication: Ensuring data is accessible in real-time across different zones for instantaneous failover
Geo-Failover: Using replication techniques to allow for operational failover to different geographical locations, allowing for operations to continue during regional incidents
Active-Active vs. Active-Passive Redundancy
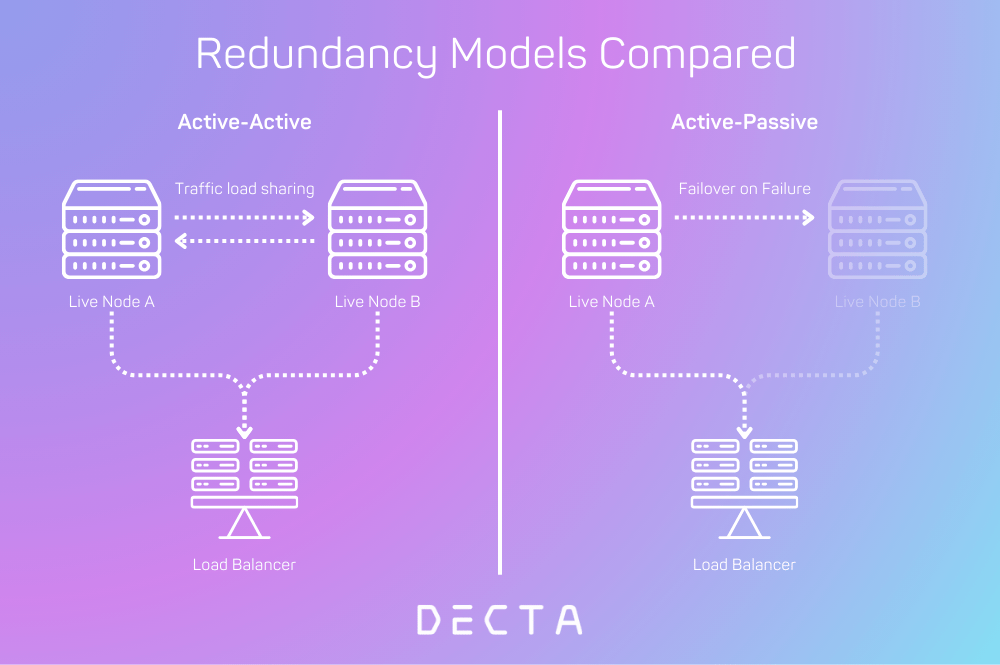
Choosing between Active-Active and Active-Passive Redundancy models determines your ability to maintain service continuity.
Active-active redundancy means that systems are always on and always available to support operations. This approach ensures real-time transaction continuity with the ability to maintain processing across multiple data centres simultaneously. Generally, having Active-Active Redundancy increases uptime and efficiency of processing tasks since systems are always operational and fully utilized.
Active-passive redundancy indicates that the systems are not used simultaneously; there will be one operating system and one backup system, functioning as a failover mechanism. This approach could be a more cost-effective option, yet it may not deliver the performance required by high-volume transaction processing environments.
The selection between these redundancy models is based on performance vs. cost trade-offs and which approach best aligns with your specific Issuer Processing requirements.
Advanced Load Balancing Strategies
Implementing advanced load-balancing strategies is crucial for maintaining high availability and optimizing transaction processing. By intelligently distributing traffic across multiple servers, load balancing reduces outages and ensures seamless service continuity. Two key techniques apply here:
L4 Load Balancing (Transport Layer): manages traffic based on network protocols
L7 Load Balancing (Application Layer): optimizes routing based on application-level data
Another step for Payment Gateway Integrations is to adopt a failover API with high API Uptime. Load Balancing prevents bottlenecks so that processing occurs with precision even during stressful Peak Transaction Handling periods.
The same principle applies to authorization switching, where authorization messages travel between the card schemes, the processor and the issuer, usually in the ISO 8583 message format or through a REST API. Redundant scheme connections and balanced switching paths mean that a single failed link does not stop authorizations from reaching the issuer.
Auto-Scaling and Predictive Capacity Planning
Auto-scaling and predictive capacity planning are essential for maintaining system performance and uptime in dynamic environments. Auto-scaling automatically adjusts resources in response to demand fluctuations, ensuring that systems operate efficiently without being overwhelmed. Predictive capacity planning enhances this by analyzing historical data and trends to anticipate future resource needs, allowing proactive scaling before demand surges.
Then there's Predictive Capacity Planning where a malleable infrastructure supports load and contributes to more stable operational performance while uptime reliability is assured. The ability to modify resources based on Demand Fluctuations and Historical Data Analysis helps prevent Over-Provisioning while ensuring Resource Forecasting accuracy.
High-Availability Databases for Payments
High-availability databases for payments are essential to ensuring seamless transaction processing and minimizing downtime. By leveraging distributed SQL databases, payment systems can achieve resilience through data replication across multiple nodes, eliminating single points of failure. This approach enhances fault tolerance, failover mechanisms, and redundancy, ensuring continuous availability even in the event of hardware or network failures.
However, increased availability also comes from Database Sharding, Database Replication, and Automatic Failover:
Database Sharding: instead of creating one large database that could take an exorbitant amount of time to access, information is parsed into smaller chunks and more accessible entry points are created.
Database Replication: ensures that information is stored in more than one place, meaning that if one place goes down, Seamless Recovery is available from the other location.
Automatic Failover: should a database go down, a backup can come online without human intervention, reducing access issues due to downtime and allowing applications to remain functional.
Real-Time Monitoring and Incident Response
Ensuring maximum uptime relies on a proactive approach that integrates real-time monitoring, incident response, and disaster recovery. Real-time monitoring enables the early detection of anomalies, allowing teams to address potential issues before they escalate.
Incident response ensures swift action to minimize disruptions, while disaster recovery strategies provide a structured approach to restoring operations after critical failures.
Implementing Proactive Monitoring for Uptime
The first way to avoid downtime is with Proactive Monitoring. With Real-Time Monitoring, you're nearly instantly notified of system health by specific Monitoring Tools. While these tools are not a guarantee that failure will never occur, they notify you of discrepancies before they become devastating problems so you can evaluate and fix the situation quickly.
With Real-Time Alerts, your team can start diagnosing and avoiding issues almost immediately, reducing your downtime and keeping you as efficient as possible. Therefore, Uptime Strategy improves when you have Performance Monitoring because, for adjustments and enhancements down the line, you already have the information in hand.
Incident Response and Disaster Recovery Planning
When an incident does occur, two targets define how quickly an issuer recovers. The Recovery Time Objective (RTO) is the maximum time a service can be unavailable before it must be restored, and the Recovery Point Objective (RPO) is the maximum amount of transaction data that can be lost, measured in time.
With only around 52 minutes of downtime allowed per year at 99.99% uptime, authorization services need an RTO measured in minutes and an RPO close to zero, which in practice means automatic failover and synchronous data replication rather than manual restores.
Regular failover drills confirm these targets hold in a real outage, not only on paper.
Security and Compliance Strategies for Card Issuers to Prevent Downtime
Security Strategies and Compliance Strategies are the next step to a dependable issuer processing solution. Nothing puts your infrastructure at risk more than security breaches or non-compliance.
DDoS Attack Prevention
Web Application Firewalls (WAF) filter, monitor, and control HTTP Traffic Filtering going to and from an application to the Internet. A WAF will block Malicious Request Blocking and help keep DDoS attacks at bay that may crash a website and bog down the infrastructure.
Zero Trust Architecture
The addition of a Zero Trust Architecture enhances your transaction processing environment by protecting you from threats from external and internal sources. You're essentially bolstering your Network Security by employing constant Access Verification and User Activity Monitoring.
PCI DSS Compliance
There exists a Security vs. Availability Balance when implementing compliance protocols. It's a requirement of PCI DSS Compliance, and while it may affect performance, the proper implementation allows for both Downtime Prevention and compliance efforts to be successful.
3D Secure and PSD2 Authentication Availability
Under PSD2, most online card payments in Europe require Strong Customer Authentication (SCA), which issuers deliver through 3D Secure. If the issuer's 3D Secure Access Control Server (ACS) or its out-of-band authentication app is unavailable, online payments fail at the authentication step even when authorization is running.
Authentication services therefore need the same redundancy and monitoring as the authorization platform, and they belong in the scope of any uptime SLA.
API Resilience
Extra security measures such as Encryption and Authentication Protocols guarantee that your APIs remain protected from unauthorized access while staying reliable during peak operational periods.
Case Study: How DECTA Achieves 99.99% Uptime
DECTA, a notable payment service provider, employs forward-thinking approaches to ensure exceptional Service Continuity.
As a certified Mastercard, Visa and UnionPay processor with PCI DSS Level 1 certification, DECTA runs its Issuer Processing platform with 99.99% certified uptime, covering authorization switching via REST API or ISO 8583, transaction processing, 3D Secure v2.2 authentication and card lifecycle management.
Multi-Region Deployments
DECTA's High Availability is a product of technology and Strategic Investments. DECTA utilizes Multi-Region Deployments, creating System Resilience with geographic Redundancy and Failover capabilities, allowing continued operations even when regional disruptions occur.
Real-Time Monitoring
Furthermore, DECTA employs 24/7 Real-Time Monitoring and Predictive Maintenance for consistent uptime. With continuous performance evaluation and AI-driven insights, DECTA can identify potential issues and implement solutions before significant problems (and downtime) occur.
Build on Resilient Payment Infrastructure
DECTA is a PCI DSS Level 1 certified processor for Mastercard, Visa and UnionPay, with issuing, acquiring and processing in one place.